How to Build a Multimodal RAG Pipeline
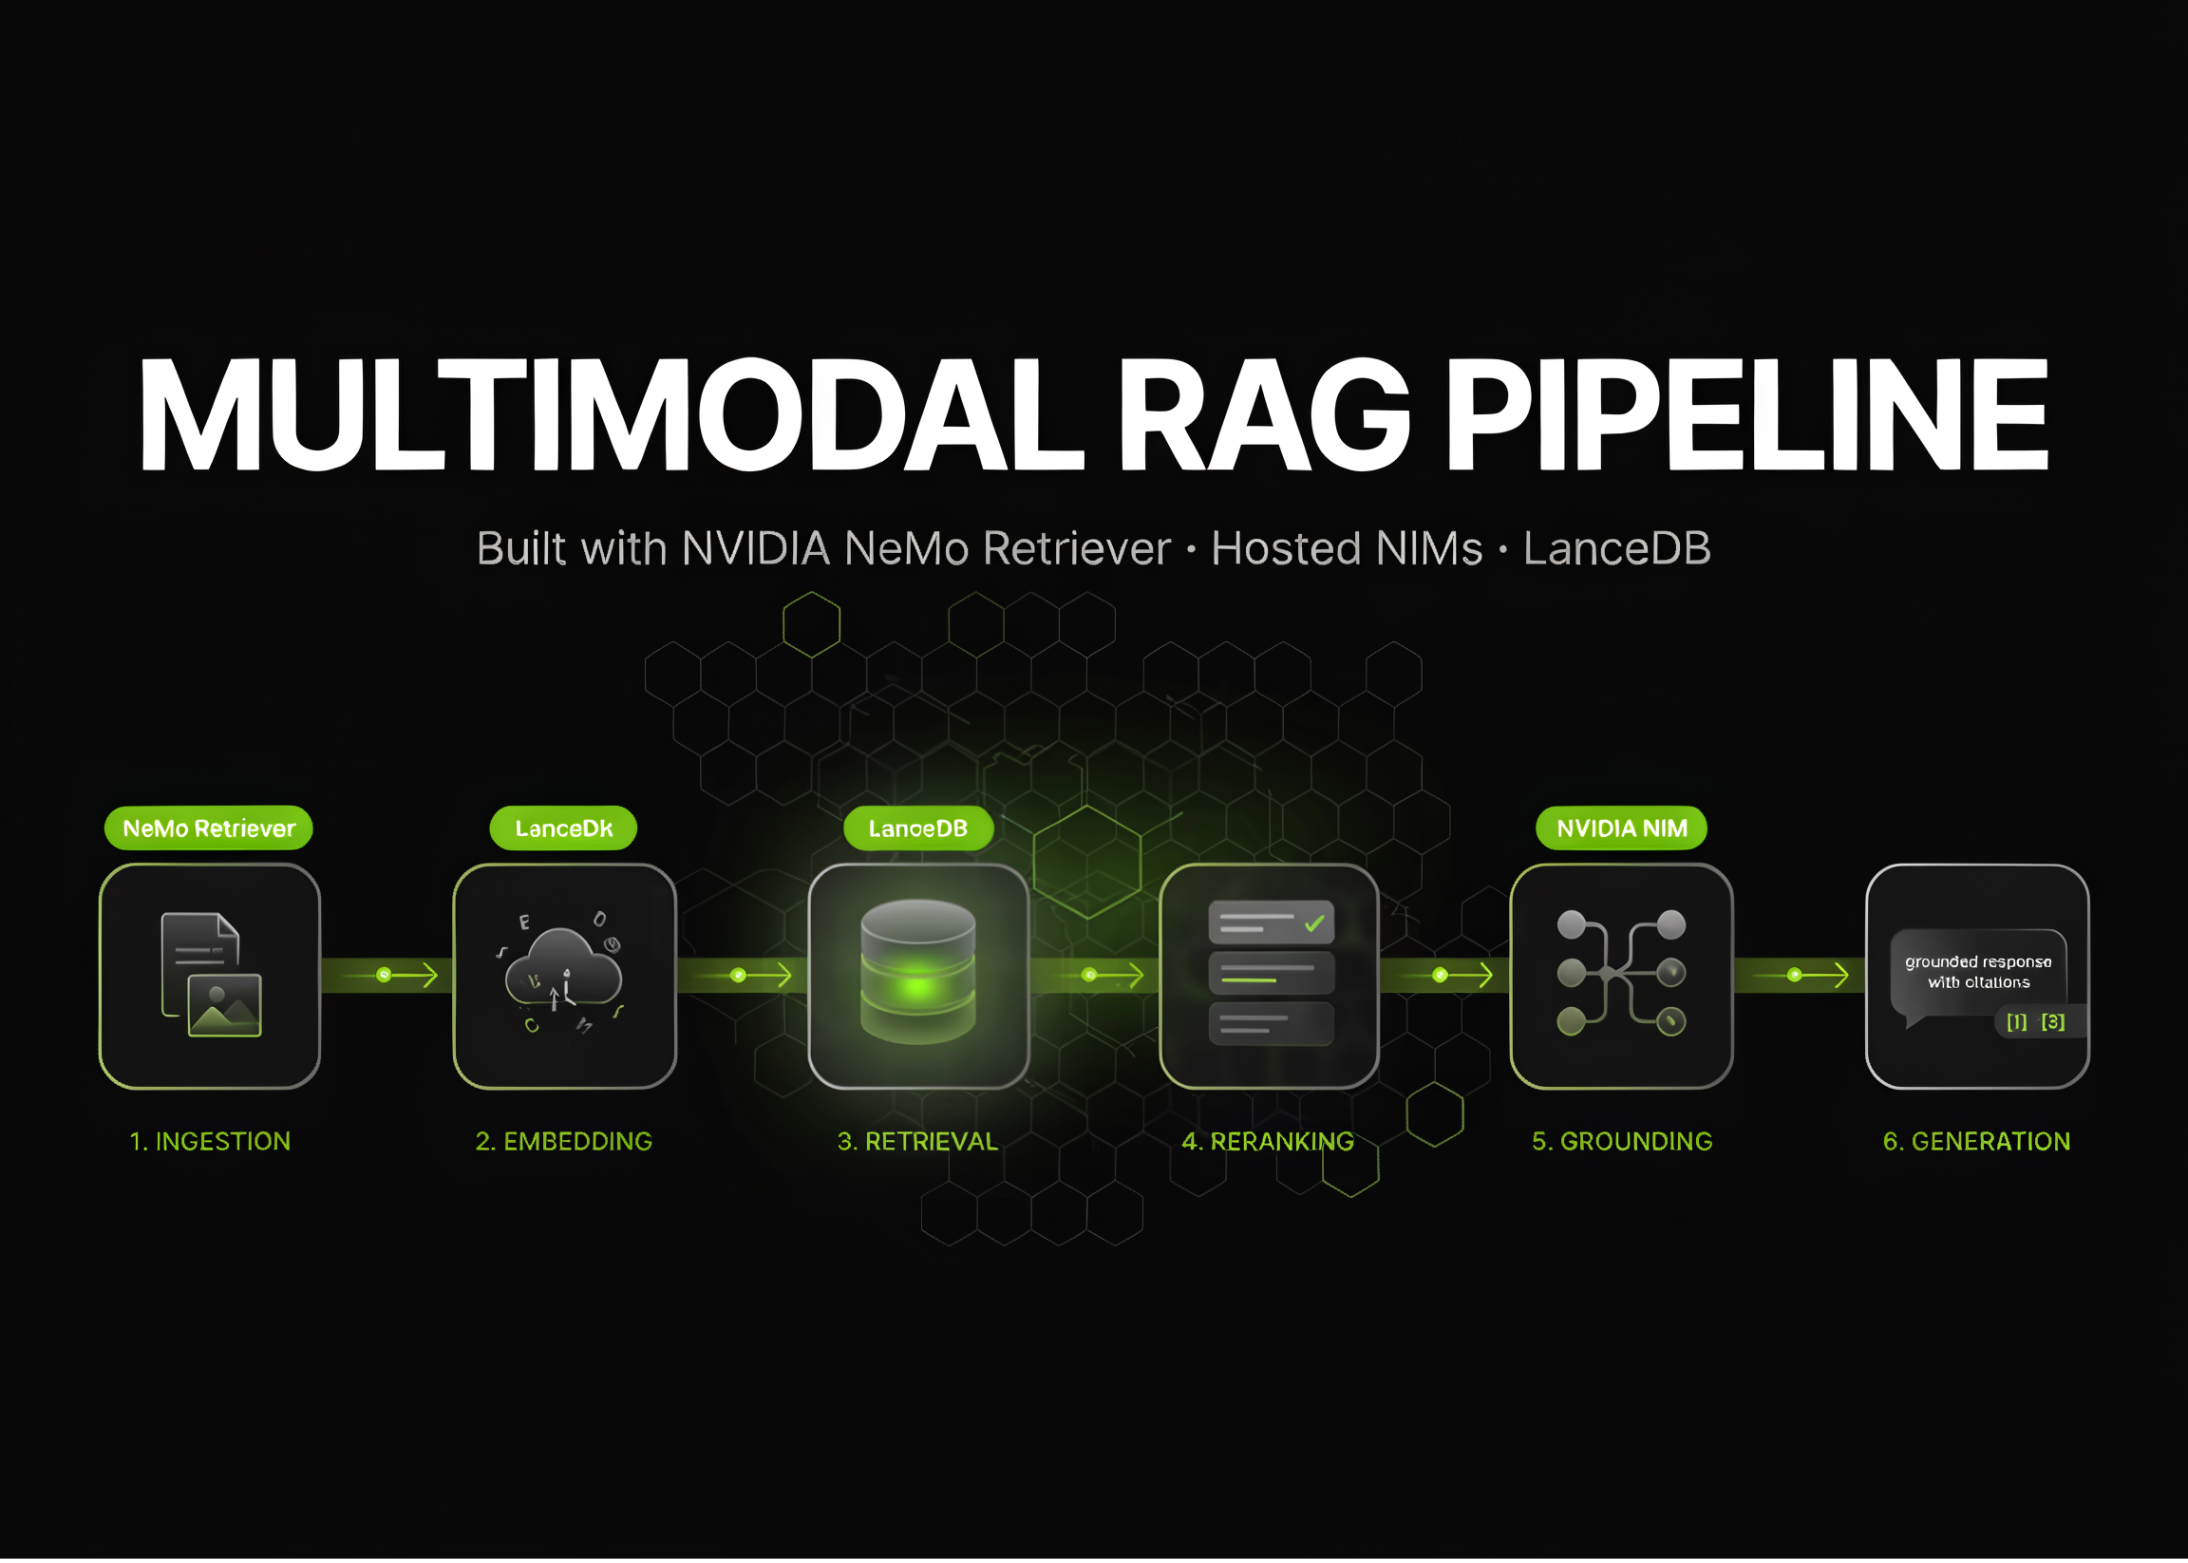
We just released a new guide on building a multimodal search pipeline. You will learn how to process PDF documents offline and set up your environment using Python. This approach avoids the need for expensive hardware or external keys during the initial extraction phase.
Our process uses NVIDIA NeMo Retriever and hosted NIM endpoints to analyze documents. We show you how to combine these tools with LanceDB to store and retrieve data effectively. Adding a reranking step helps improve the accuracy of your results significantly.
This workflow concludes by using grounded generation to provide clear answers based on your source files. It is a great way to handle complex documents that contain both text and images. Check out the full post to follow the step by step instructions.
Comments (0)
No comments yet. Be the first!
More AI news
 News
New AI Tool Fixes Mistakes in Financial Research
Researchers developed a new framework to stop AI from learning from its own bad data in financial trading models.
 News
Perplexity adds local AI to Mac apps
The new update lets your Mac handle some AI tasks directly on your computer.
 News
Meta Releases Muse Image Model on Fal
Meta has launched a new AI model on the Fal platform that plans and edits images on its own.