How to Fine Tune Language Models Using DPO
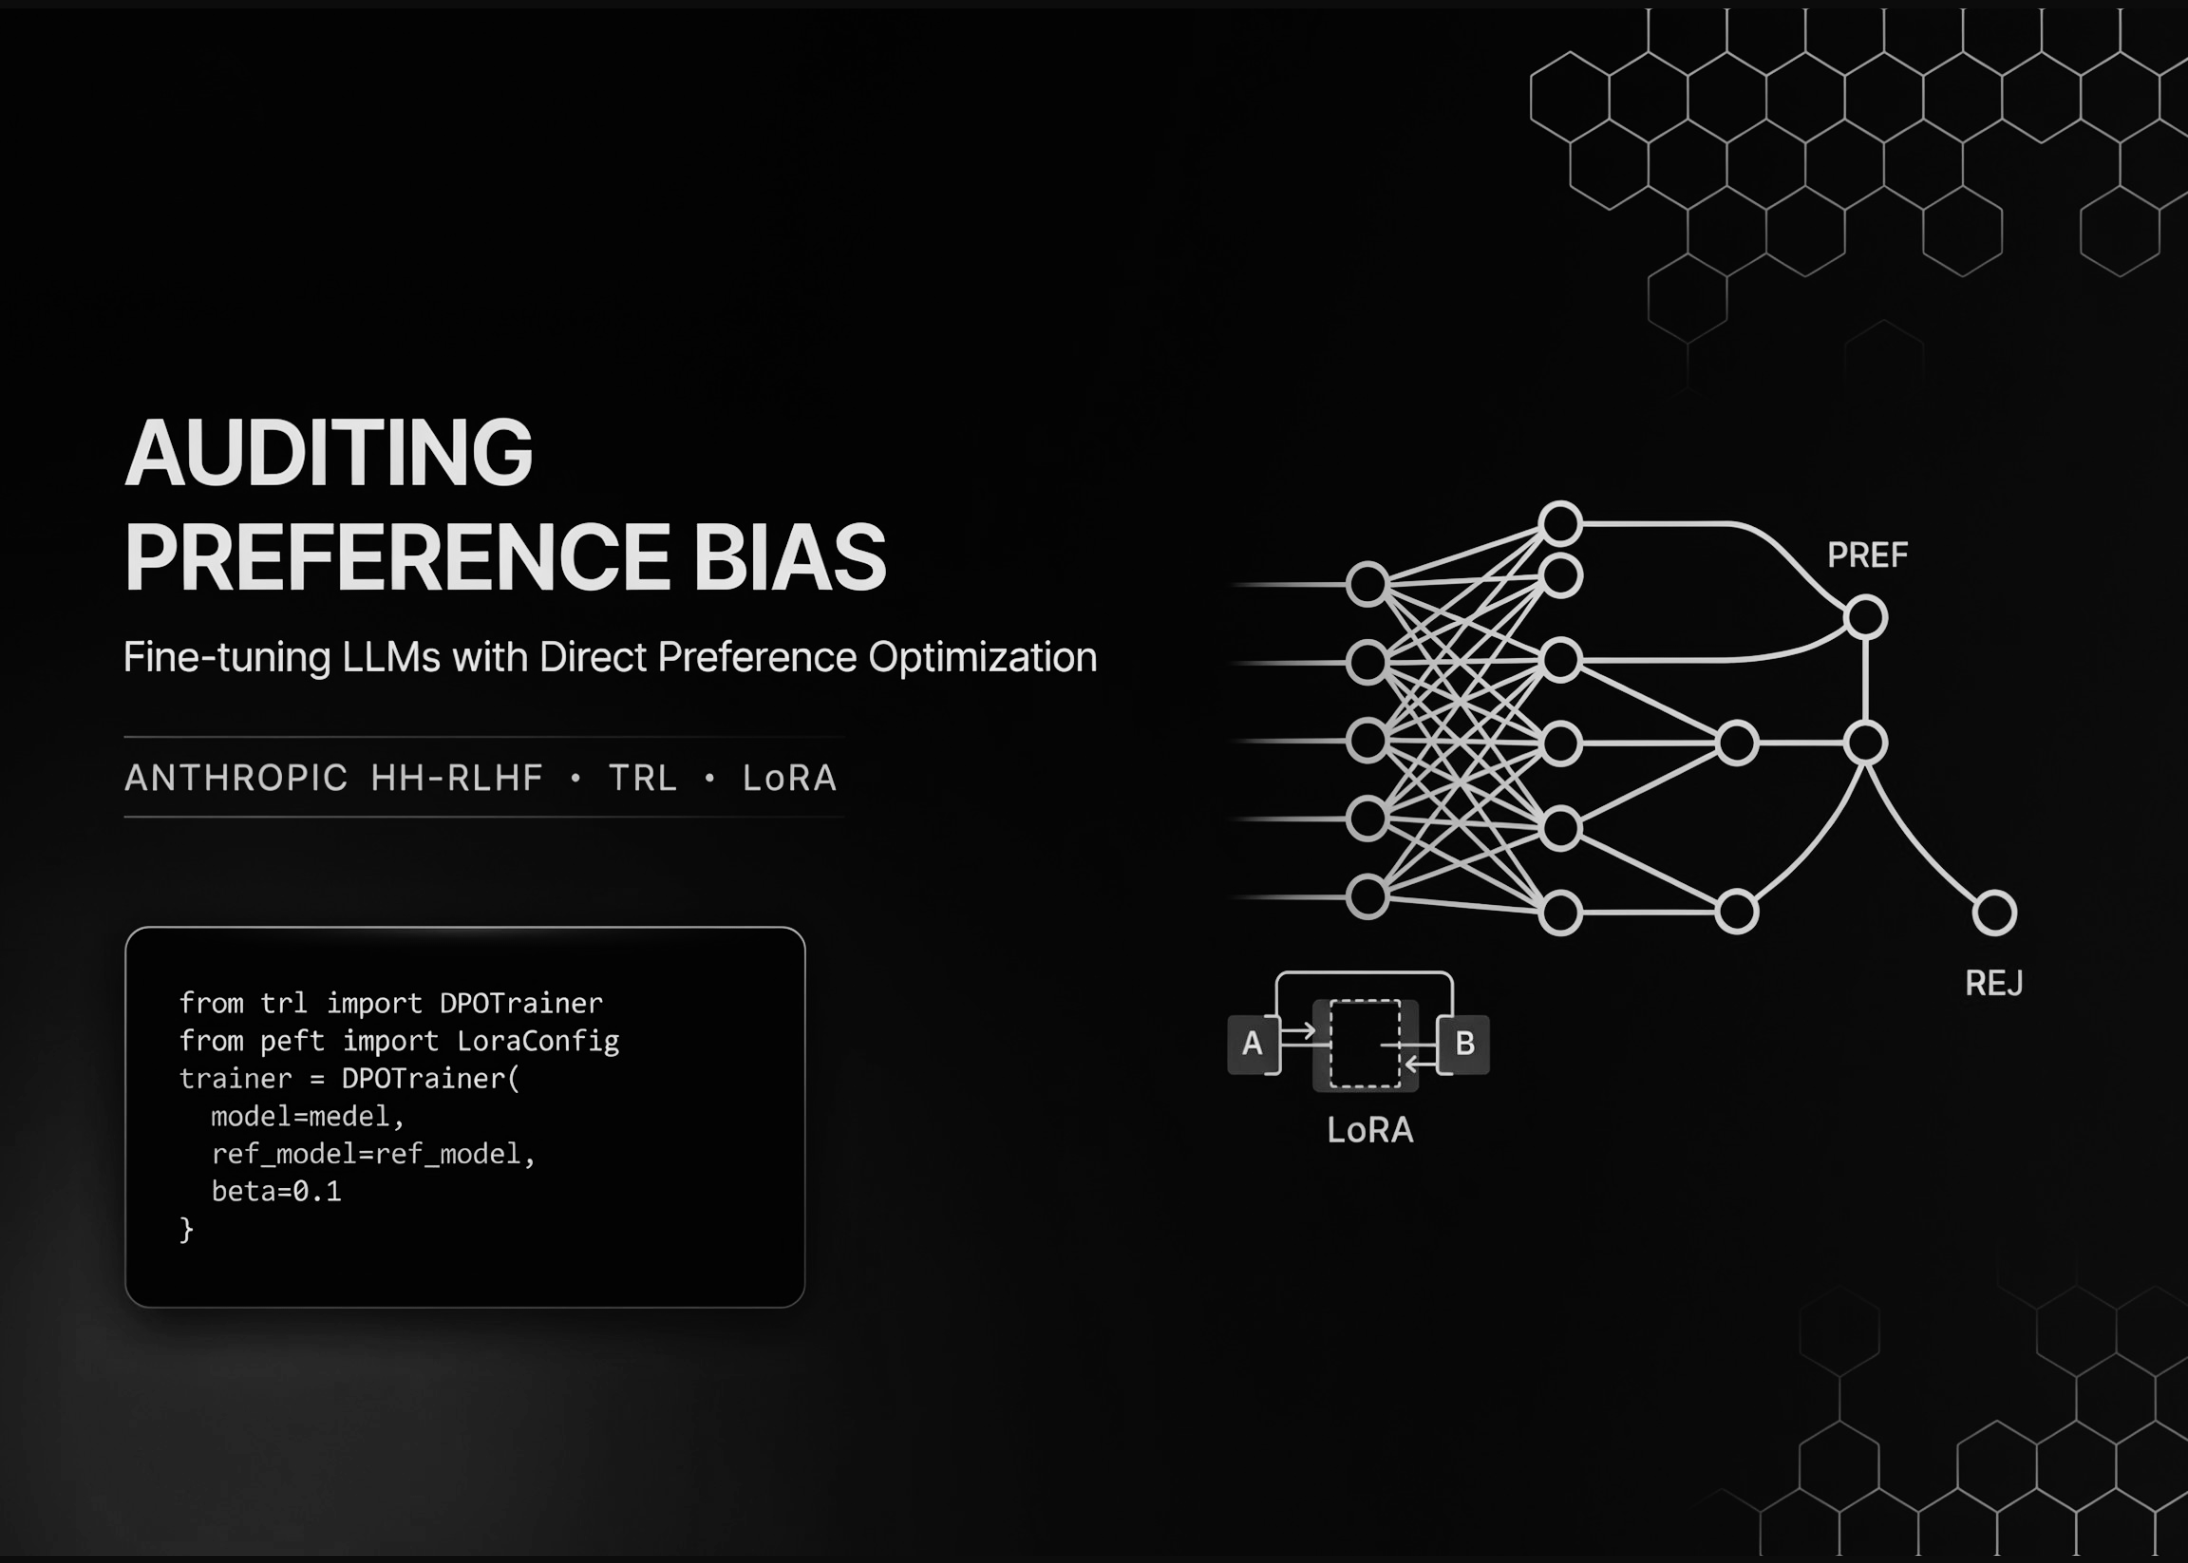
Language models often pick up bad habits from their training data. We show you how to check for these biases in the Anthropic dataset. Specifically, we look for cases where the model prefers longer answers regardless of quality.
Our process uses tools like TRL and LoRA to keep things efficient. This setup lets you train models on consumer hardware without needing massive resources. We walk through the entire pipeline step by step.
The goal is to teach the model to learn actual user preferences. By following these steps, you can stop the model from taking shortcuts. Your final result will be a smarter and more reliable assistant.
Comments (0)
No comments yet. Be the first!
More AI news
 News
New AI Tool Fixes Mistakes in Financial Research
Researchers developed a new framework to stop AI from learning from its own bad data in financial trading models.
 News
Perplexity adds local AI to Mac apps
The new update lets your Mac handle some AI tasks directly on your computer.
 News
Meta Releases Muse Image Model on Fal
Meta has launched a new AI model on the Fal platform that plans and edits images on its own.