IBM Releases Blazing Fast Audio Transcription Model
The new Granite Speech 5.0 models are incredibly small but powerful. Each one uses only 470 million parameters to handle massive amounts of audio data. Because they are so lightweight, they run faster than any other open model currently available.
On a single NVIDIA H200 chip, this system processes over 3.5 hours of audio in just one second. This speed is roughly twelve thousand times faster than real time. It marks a significant jump in how quickly computers can convert spoken words into text.
This update helps developers process large audio files without needing massive computing power. You can now transcribe long recordings almost instantly. It is a major step forward for anyone working with voice data or automated documentation.
Comments (0)
No comments yet. Be the first!
More AI news
 News
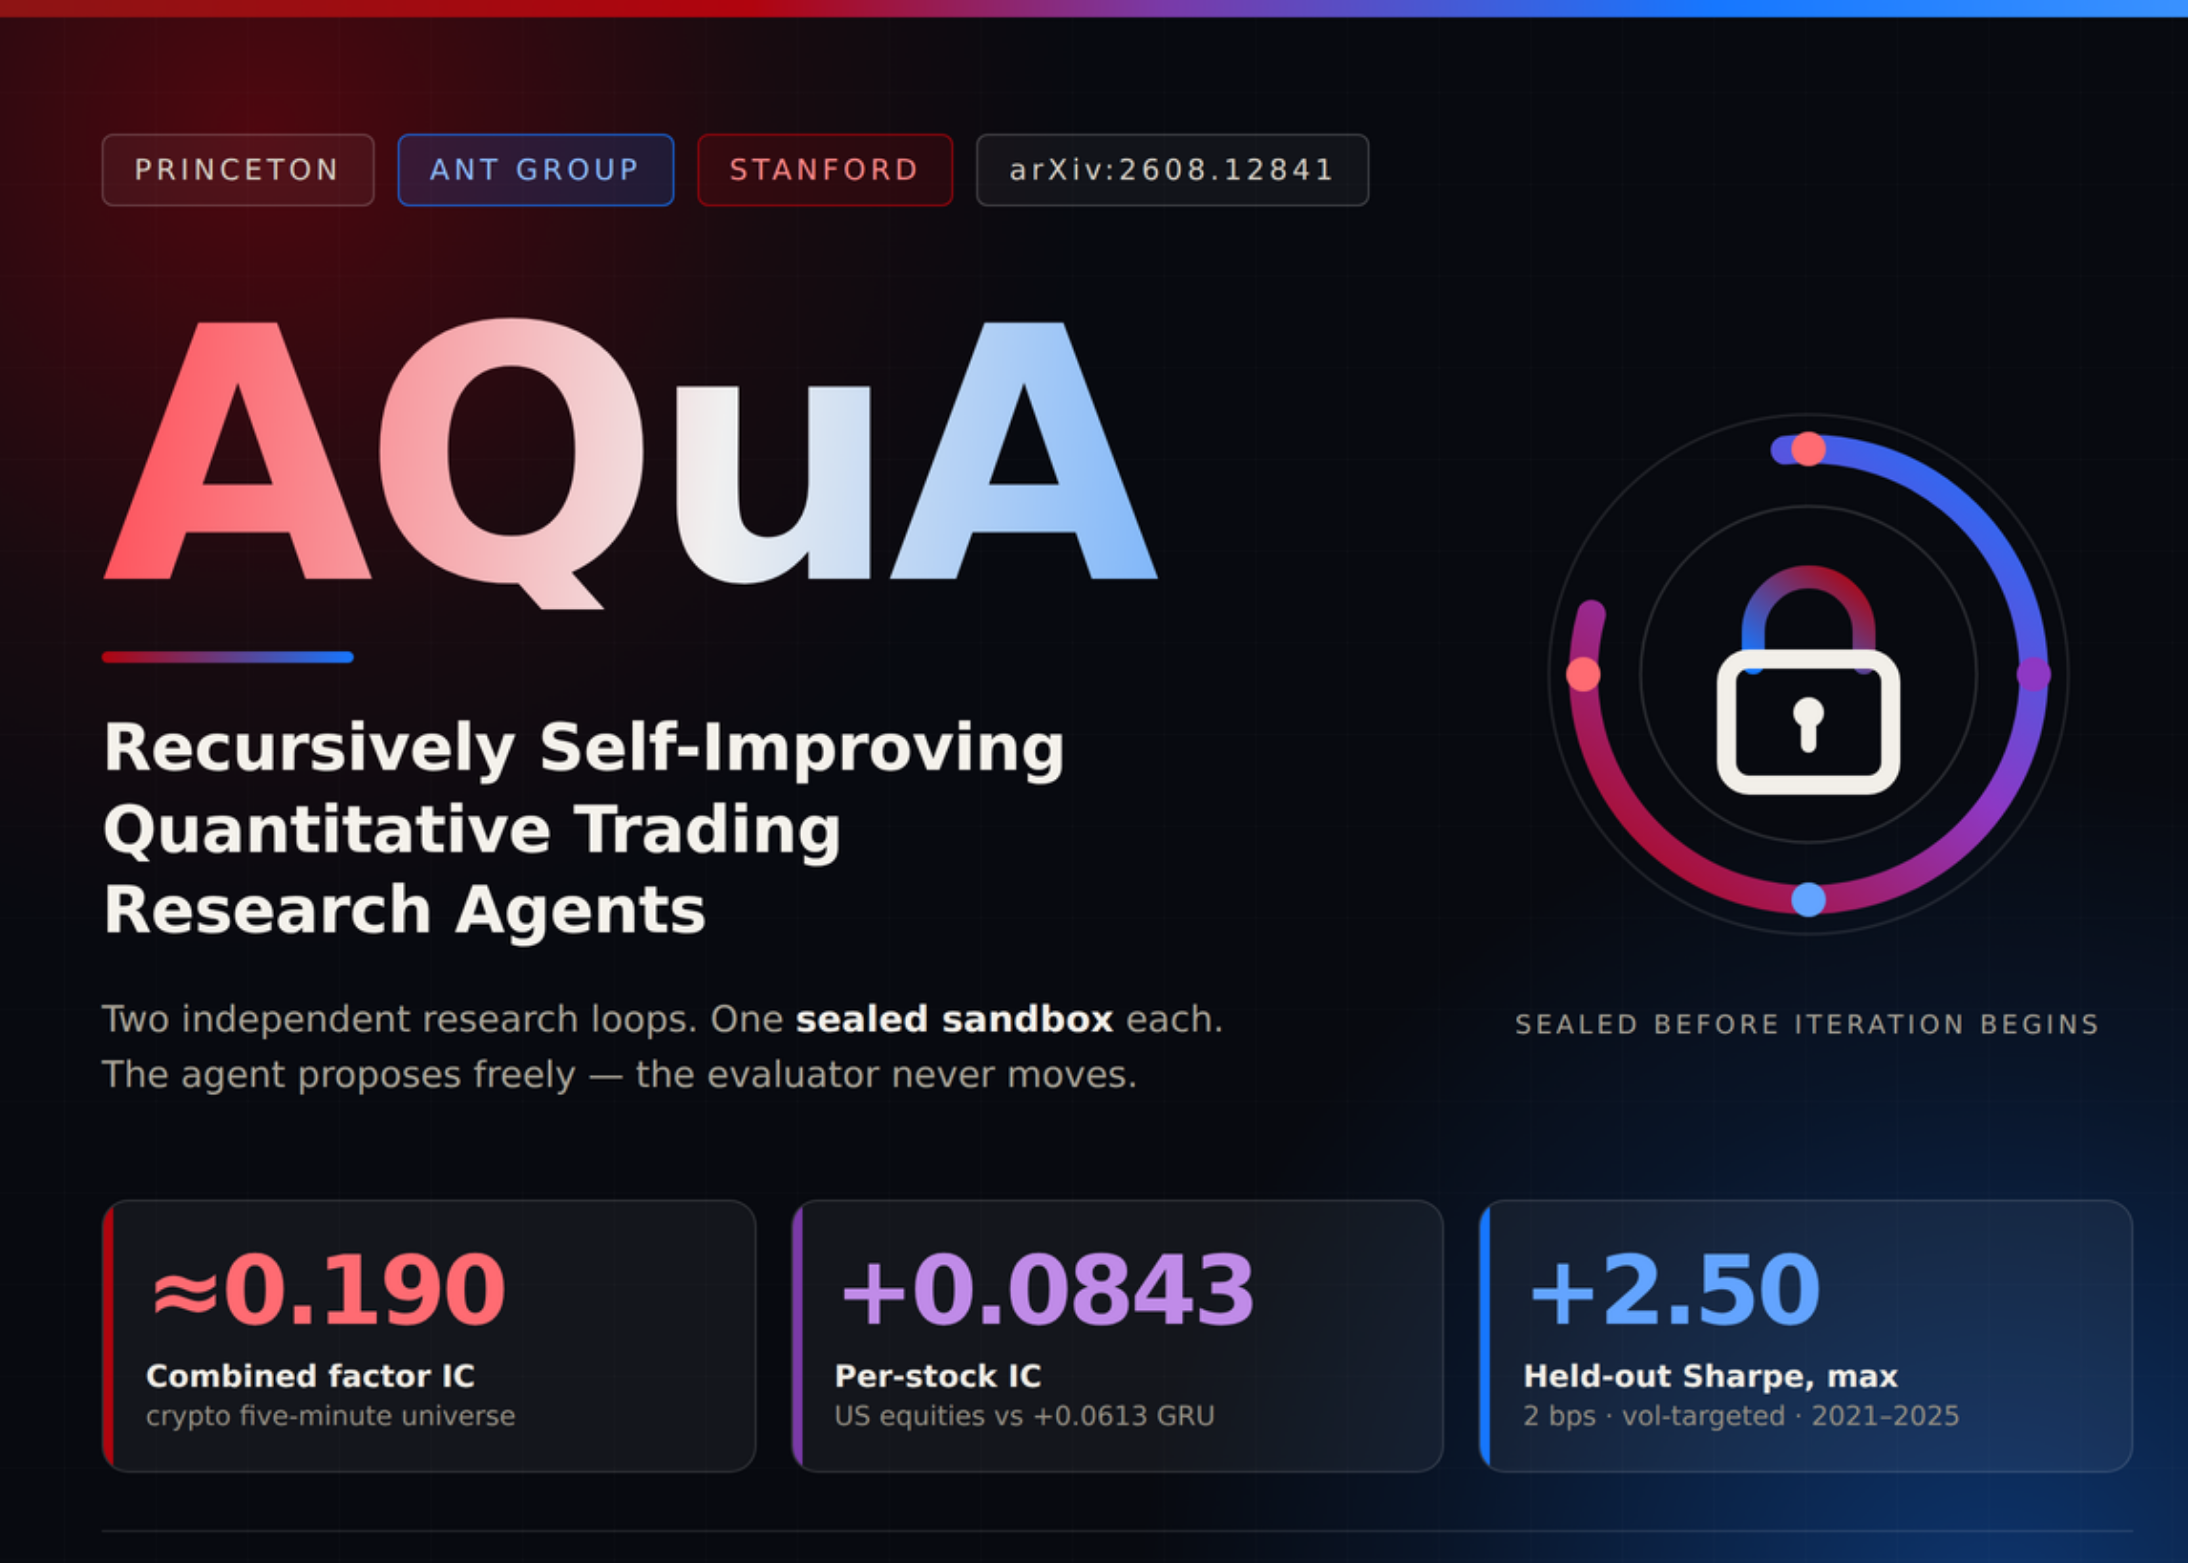
New AI Tool Fixes Mistakes in Financial Research
Researchers developed a new framework to stop AI from learning from its own bad data in financial trading models.
 News
Perplexity adds local AI to Mac apps
The new update lets your Mac handle some AI tasks directly on your computer.
 News
Meta Releases Muse Image Model on Fal
Meta has launched a new AI model on the Fal platform that plans and edits images on its own.